Cost-Efficient Resource Allocation Technique using Bayesian Optimization in Serverless Environment
Korea Computer Congress (KCC 2024)
Memory-only tuning misses options on platforms with independent CPU settings. We searched CPU and memory jointly over configurations supported by the platform.
- Role
- Co-author · serverless resource-allocation research
- Outcome
- Found the optimum at iterations 17 and 13 in a 36-configuration GCF search; CPU-bound cost was about 9.43% below the minimum-resource configuration.
Background
Serverless functions are cost-efficient — no infrastructure to manage, billed only while running — but how much memory and vCPU each function gets decides its performance and cost. Both over- and under-allocation hurt, and the right value is hard to find. Prior work COSE uses Bayesian optimization to predict execution time and cost and pick an optimal memory setting — but it tunes memory alone.
AWS Lambda scales vCPU with memory, but on platforms like Google Cloud Functions and Knative that set memory and vCPU independently, tuning memory alone (COSE) misses cheaper combinations.
Approach
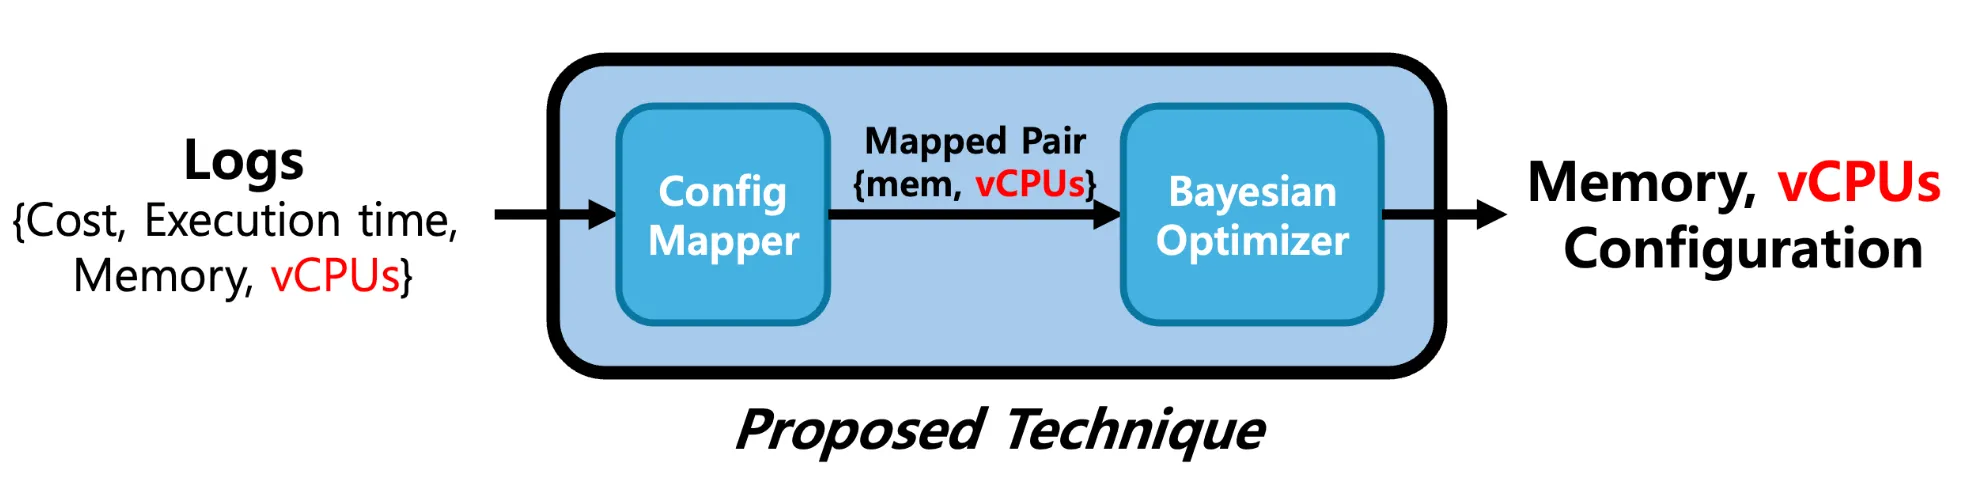
The method extends COSE to treat memory and vCPU as two independent variables for Bayesian optimization. Since tuning resources at 1 MiB granularity buys little, the search space is defined discretely, and a Config Mapper normalizes continuous inputs and maps them to the nearest discrete combination. The acquisition function is EI (Expected Improvement); once EI falls below 5% of its maximum, the search is deemed converged and the lowest-cost setting is adopted. Switching the objective to cost × latency can instead steer toward fast, cheap settings.
Results
Using the 36 CPU–memory configurations supported by Google Cloud Functions at the time, CPU- and memory-intensive functions were each measured ten times. The optimizer found the best configurations at iterations 17 and 13. CPU-bound cost was about 9.43% below the minimum-resource configuration.
The objective minimized cost without a latency constraint. More CPU could shorten execution enough to offset its higher unit price. SLO-constrained optimization and evaluation on other platforms remained follow-up work.